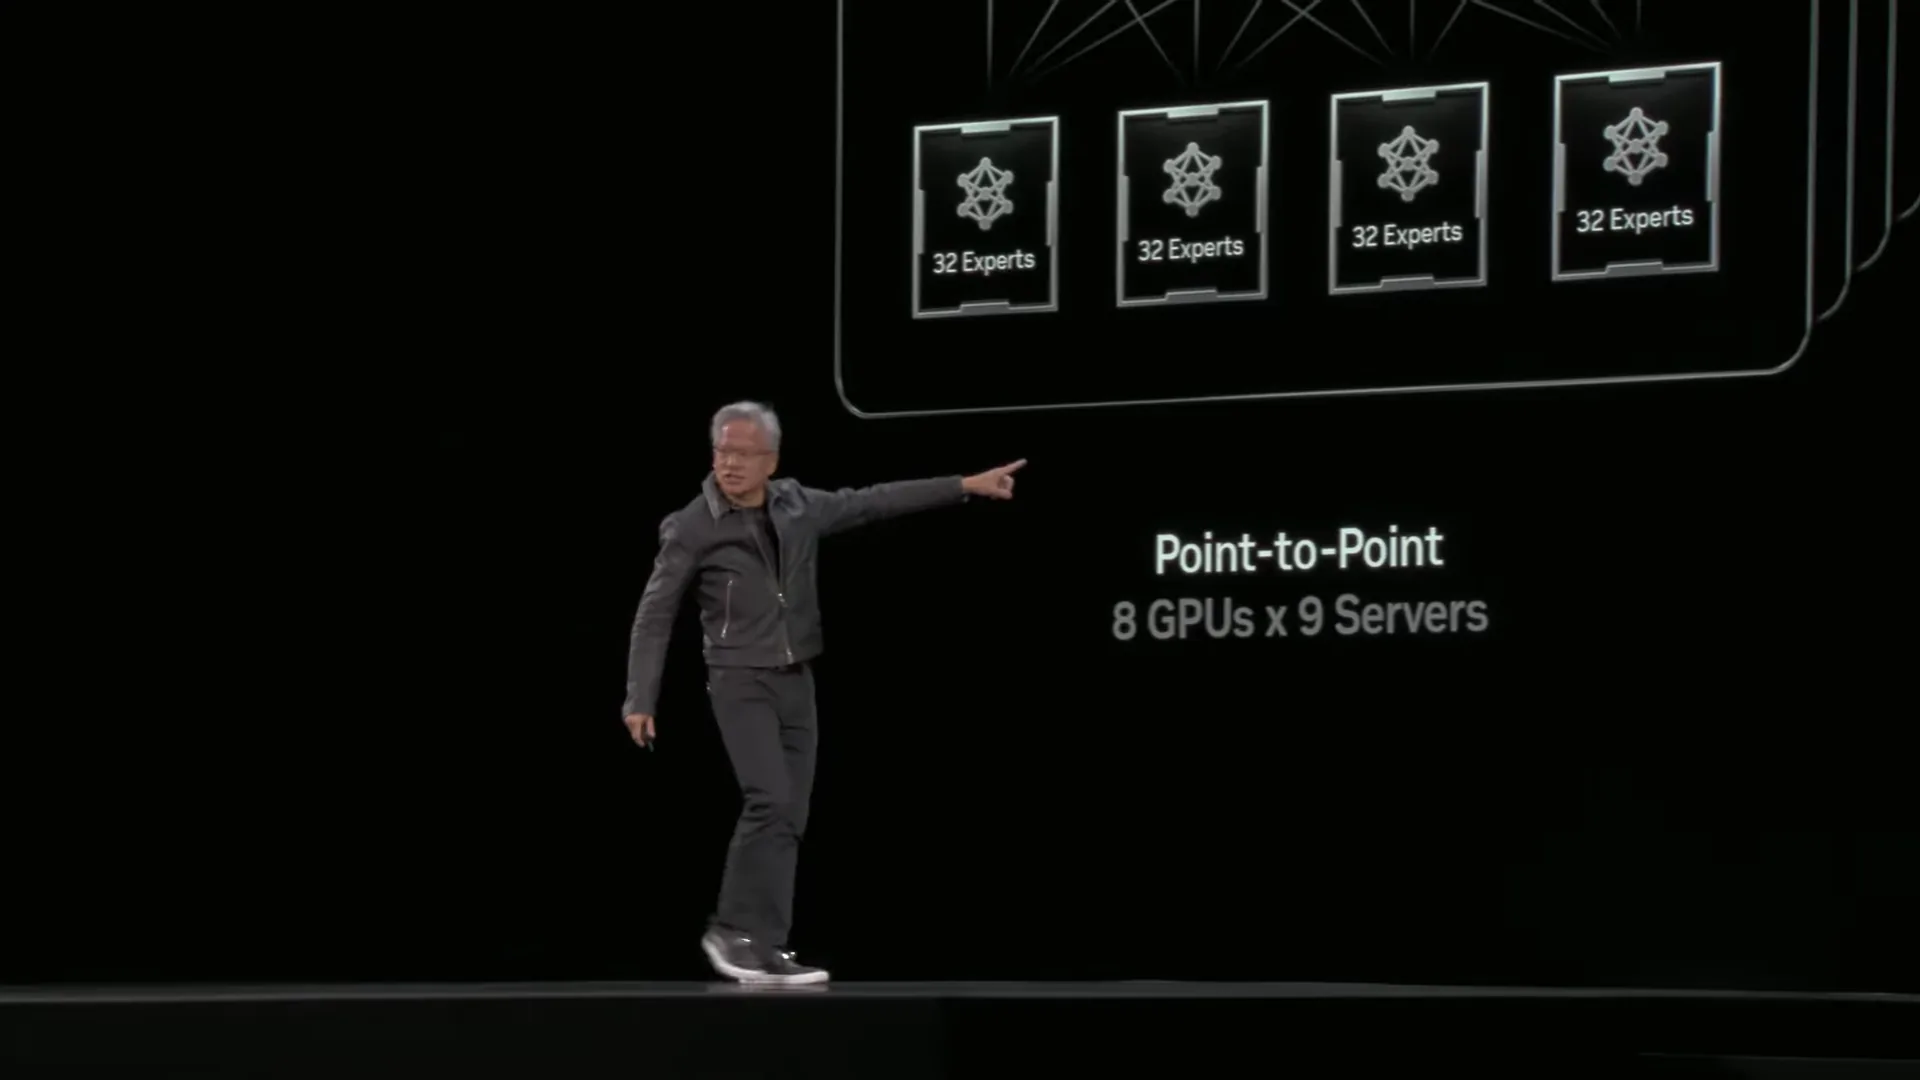
Agentic AI: 8 GPUs, 32 experts each
When the new chips arrive in about a year, the update the models get is hard to imagine.
We are in the Blackwell 2-year frame. When new chips arrive in about a year, LLM models get an update unimaginable.
NVIDIA’s next chip, Rubin, will include everything we have learned since ChatGPT went global.
The new scale for running massive mixture-of-experts models:
→ 8 GPUs × 9 Servers (Point-to-Point via Ethernet)
→ Each GPU represents 32 Experts
This is the physical backbone for agentic AI at scale.
Slide: point-to-point, 8 GPUs × 9 servers, 32 experts each, from the GTC Washington keynote at 54:45.